Wiki › Project
Claim Conflict Finder
Article
ReadAll pages
From Chaipat's knowledge graph
Claim Conflict Finder is a free, open-source agent skill that shows where research papers disagree, and whether different datasets, populations or methods explain the disagreement. It is the middle step of the Research Suite, between Paper Scout and Research Dossier.
How it works
- The agent extracts claims. It reads each paper and records its main findings as structured claims. Each claim has:
- a subject, a relation and an object;
- a direction, a metric and values;
- the dataset, population, method and conditions;
- a verbatim quote of up to 25 words, and where in the paper it came from.
- A script aligns and compares them.
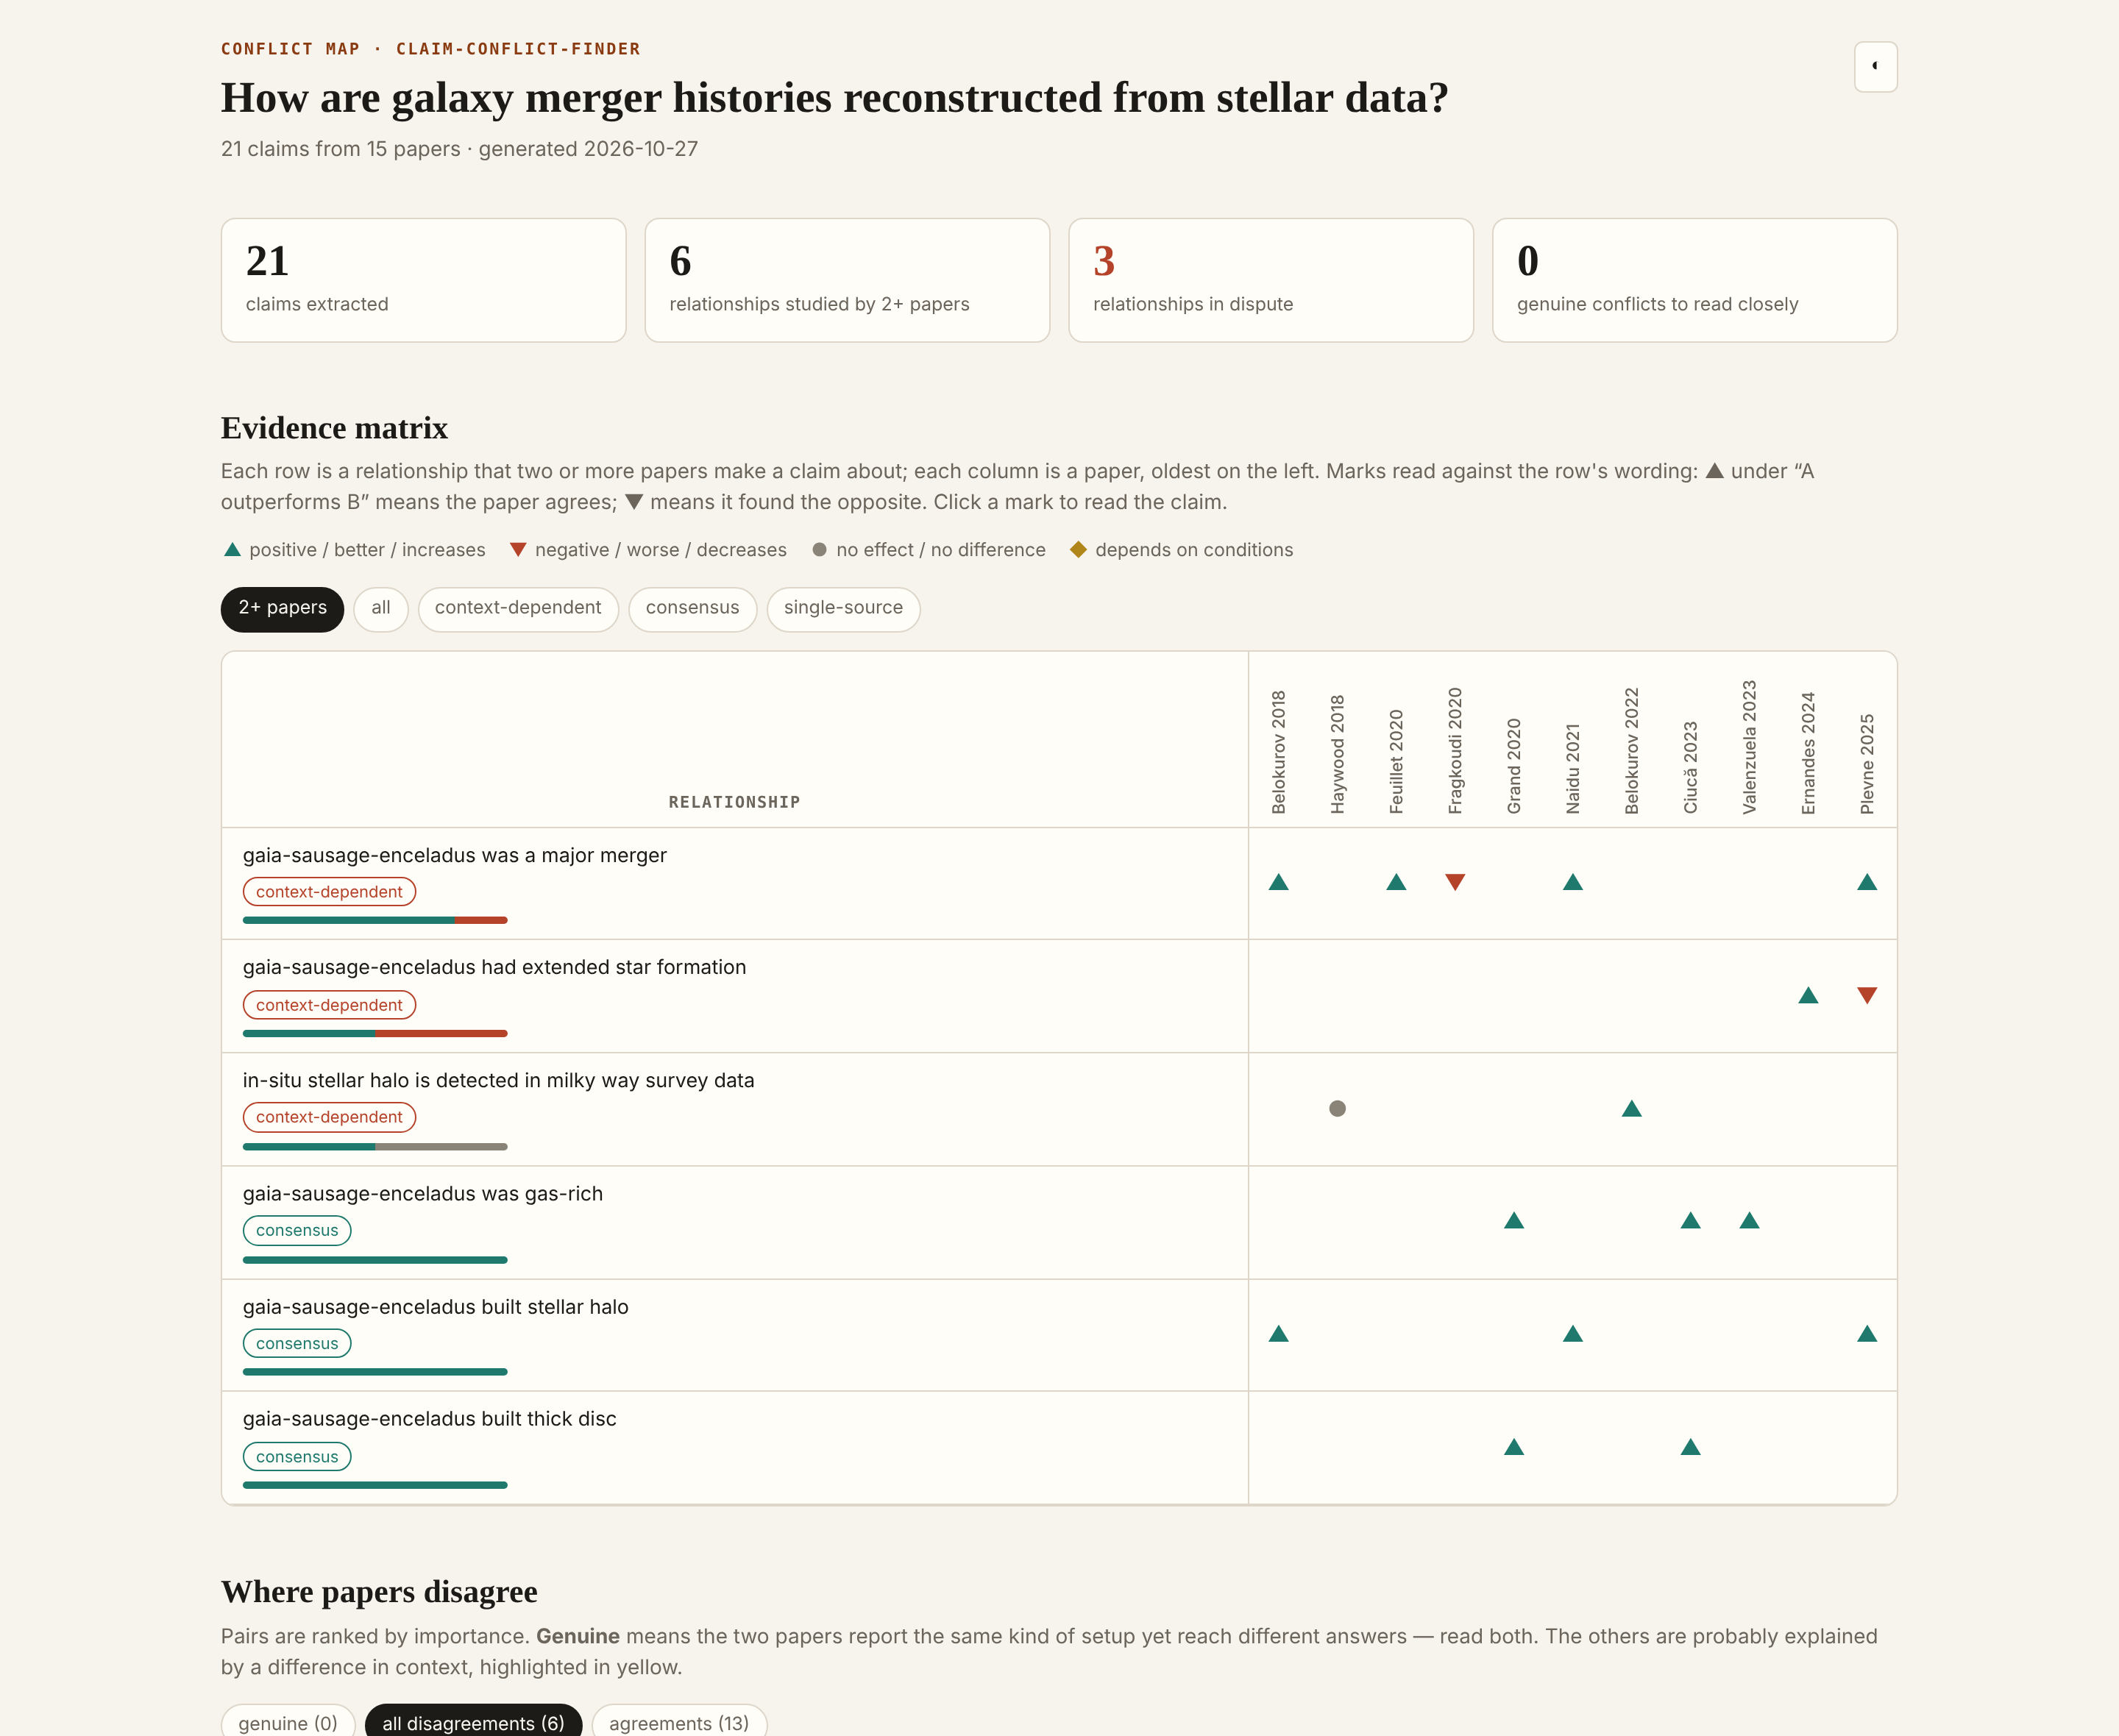
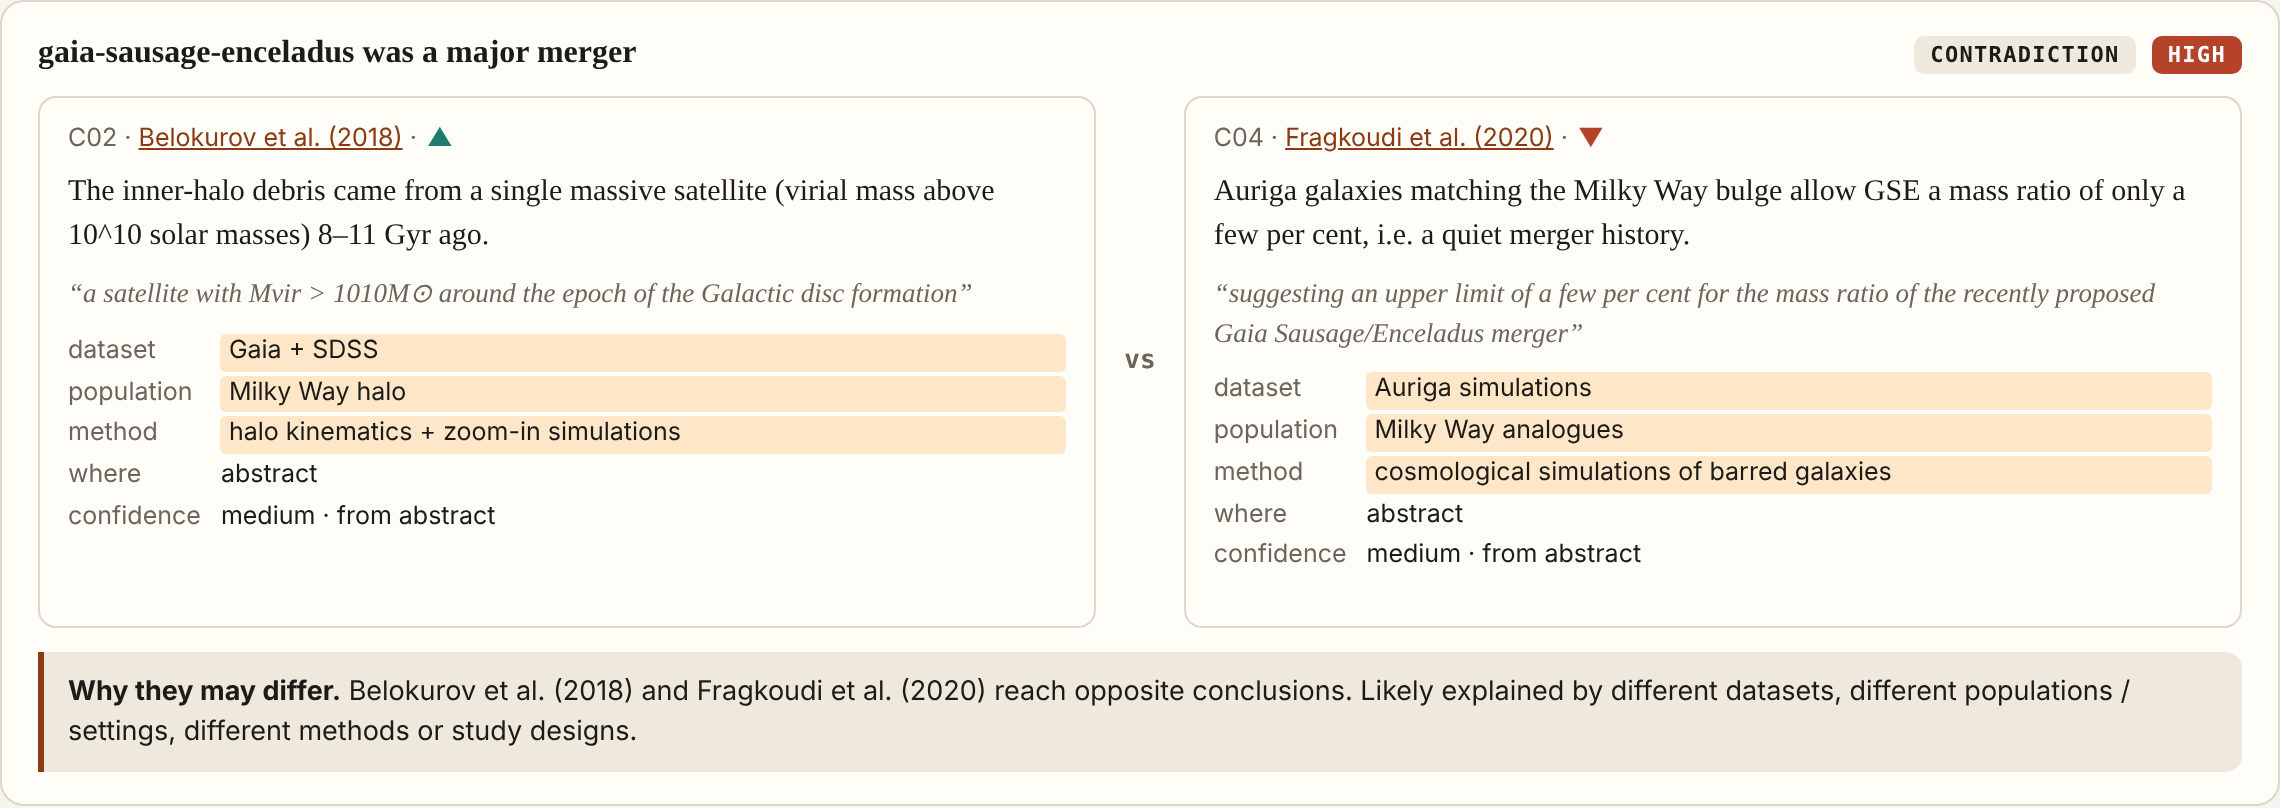
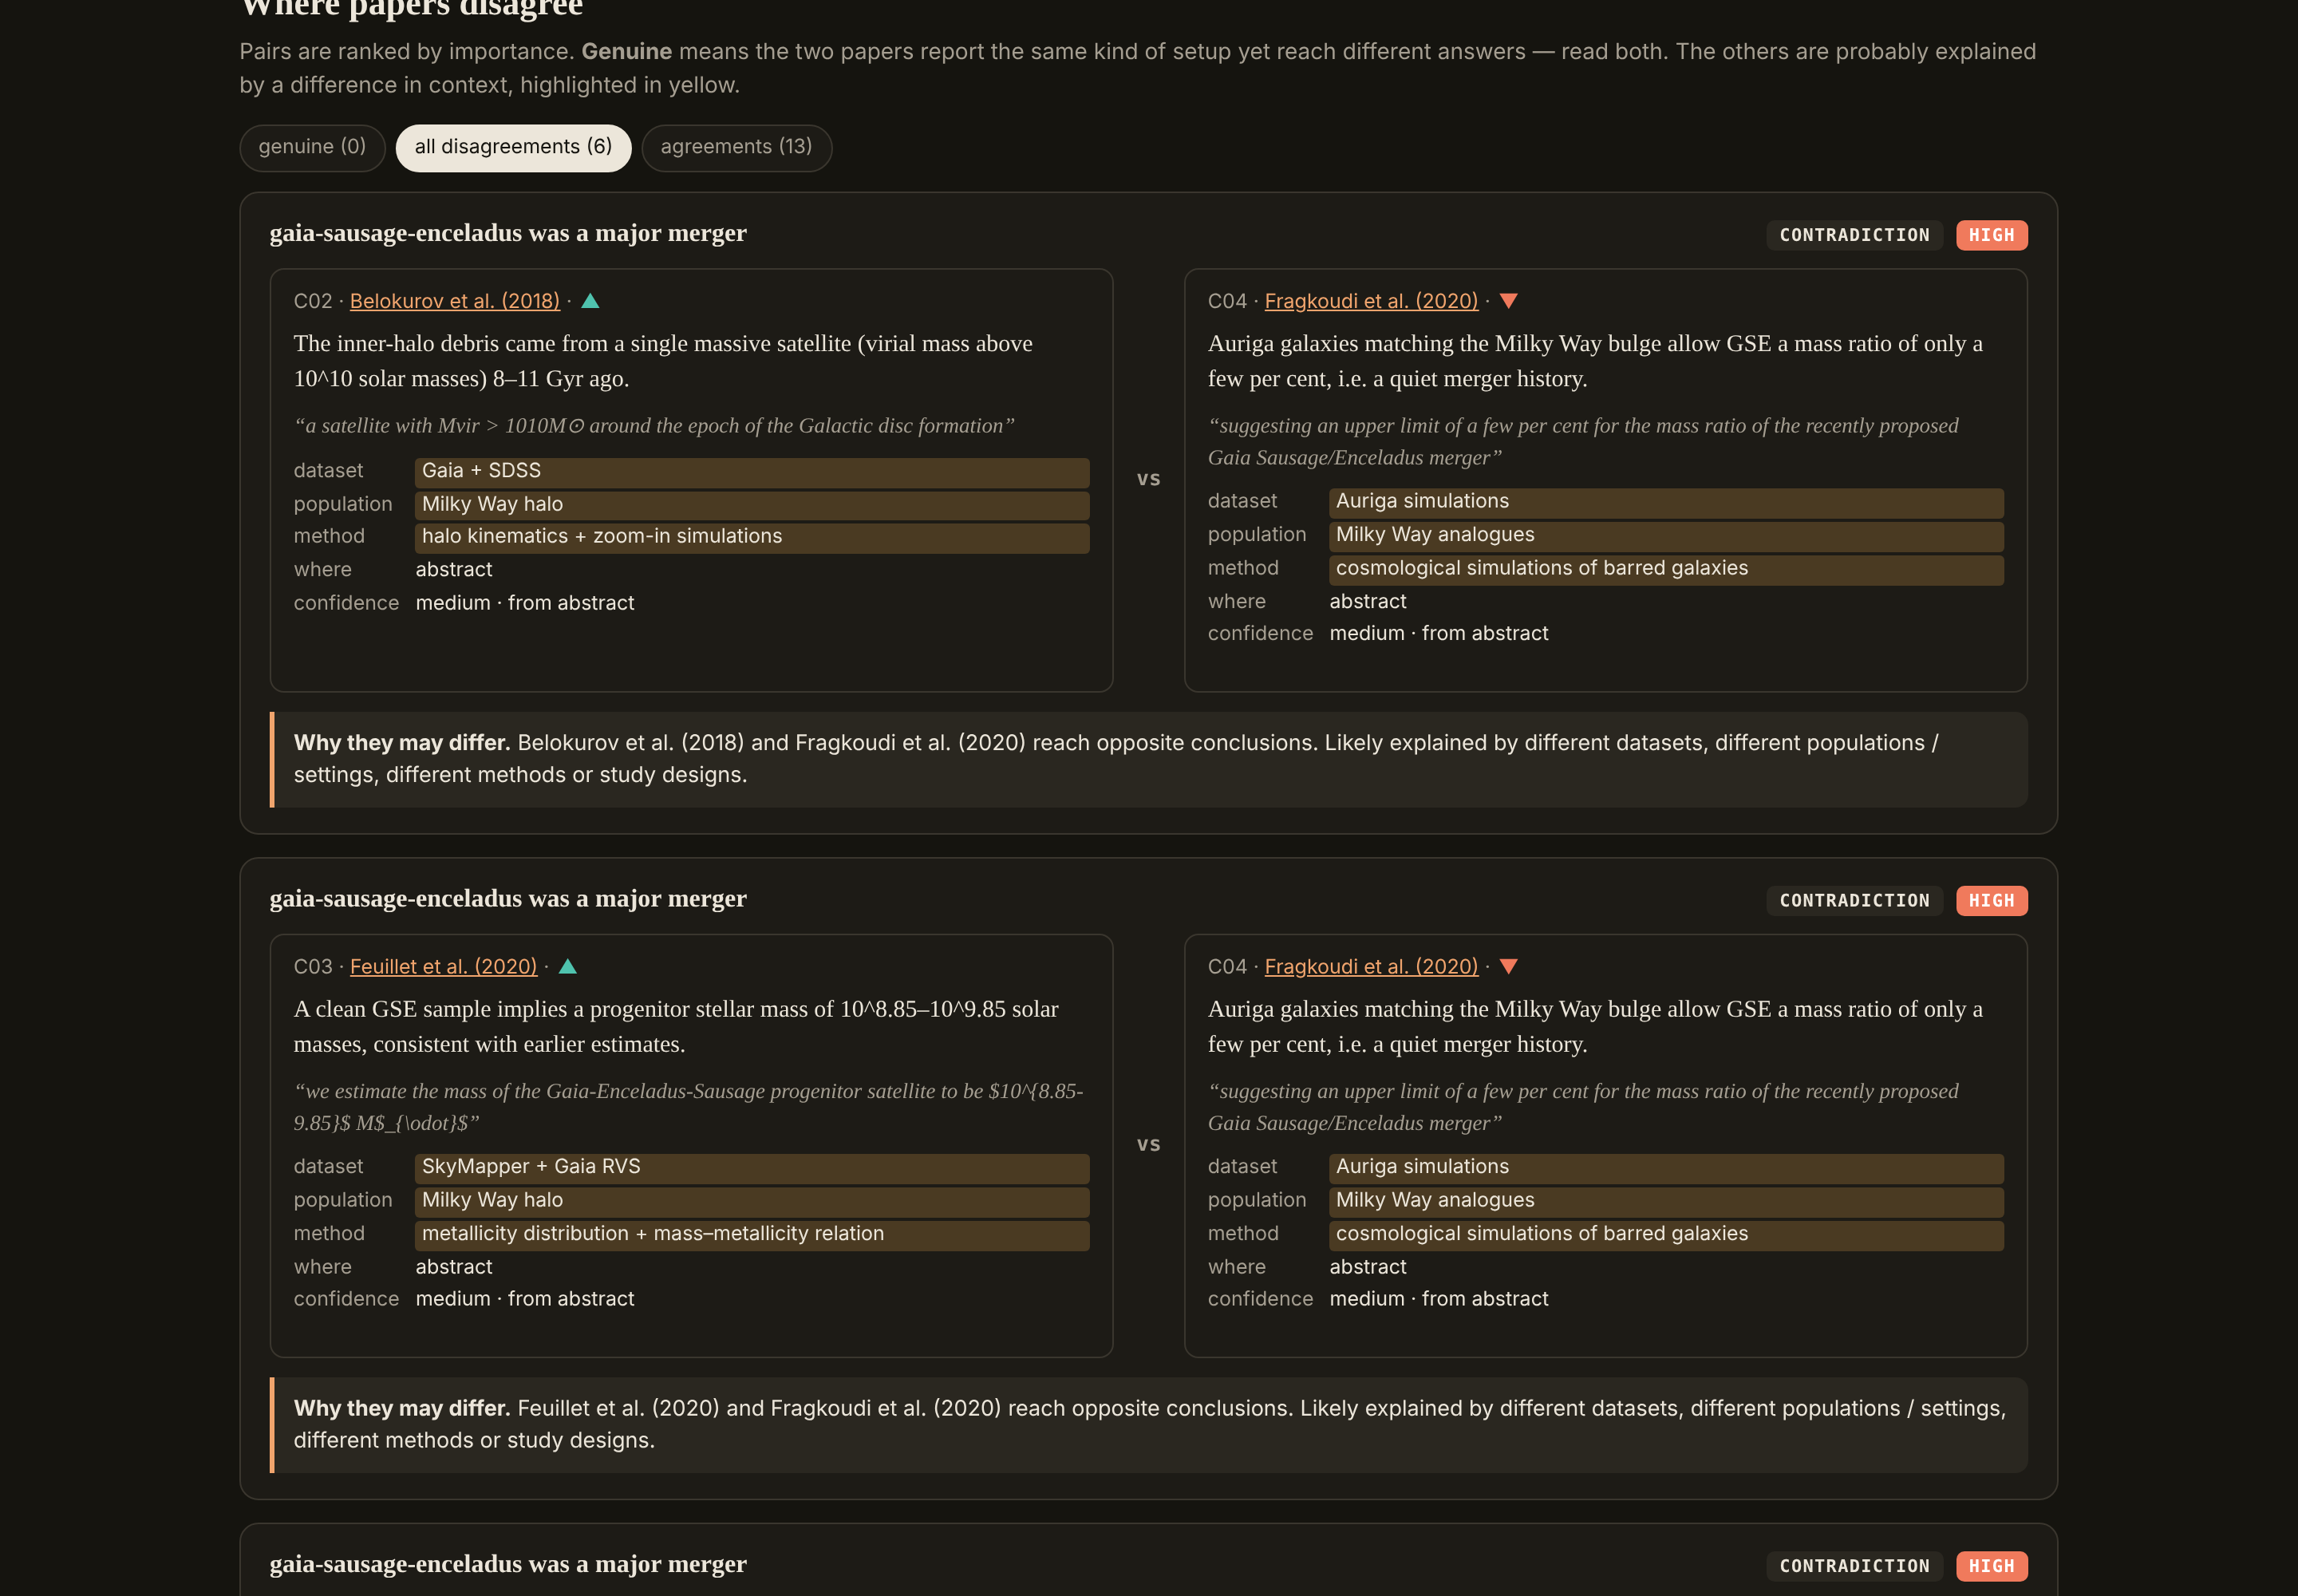
scripts/conflicts.py, in Python, matches equivalent claims: synonyms, plurals, and reversed statements, so "B underperforms A" matches "A outperforms B". It compares every pair across papers and labels it a contradiction, null versus effect, magnitude, conditional or agreement. - Each disagreement gets a verdict. It is either genuine (the same setup gives a different answer, so read both papers) or explained by a recorded difference in context. Either way it comes with a plain-English explanation and a severity.
Outputs
| File | What it is |
|---|---|
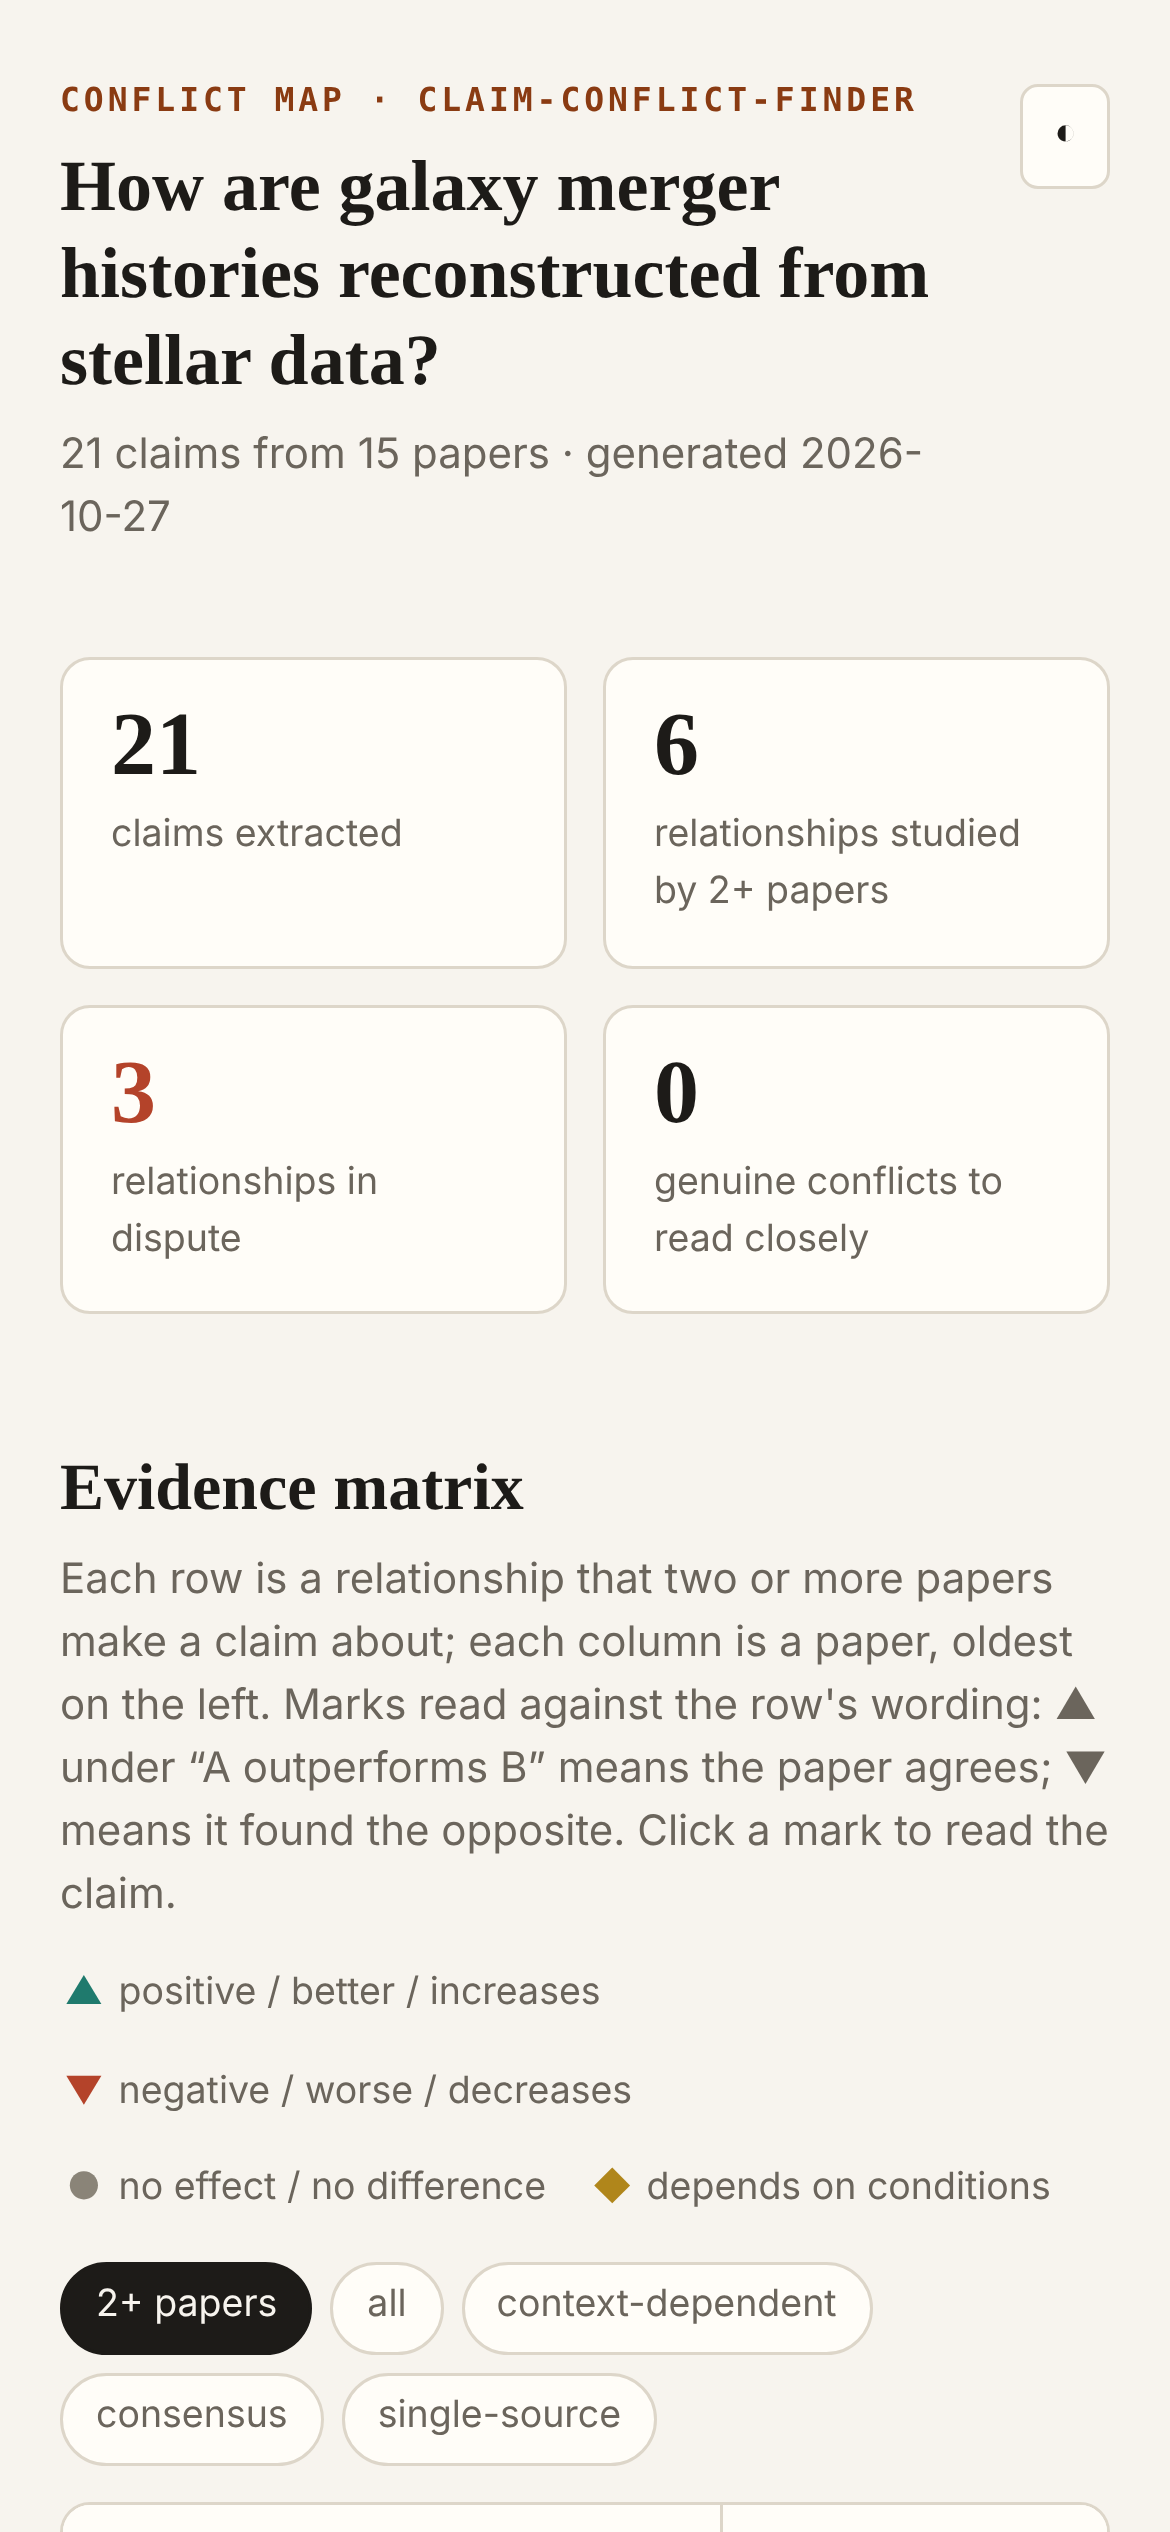
conflict_map.html | An interactive evidence matrix (relationships × papers) and side-by-side conflict cards; offline, light and dark, mobile-friendly |
conflicts.md | A readable report, most important disagreements first |
conflicts.json | Every topic and compared pair, machine-readable |
claims.ttl | An RDF/Turtle knowledge graph of papers, claims and concepts, linked by conflictsWith and agreesWith, ready to query with SPARQL |
The Turtle export makes the skill a small piece of ontology engineering. It turns a literature review into a graph that a triple store can reason over. The script makes no network requests.
See also
Pictures